平时我们经常需要对我们的数据集进行各种分析,以便我们找到更好的提高方式。所以我将我平时分析数据集的一些方法打包发布在了Github上,分享给大家,有什么错误和意见,请多多指教!
项目地址
这些信息会在终端打印出来,格式如下:
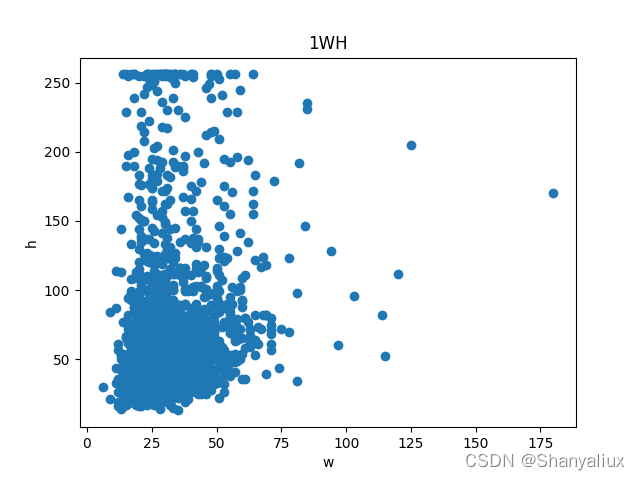
number of images: 6666number of boxes: 19958classes = ['4', '2', '1', '3']这里只有一个点,是因为所有的图片尺寸相同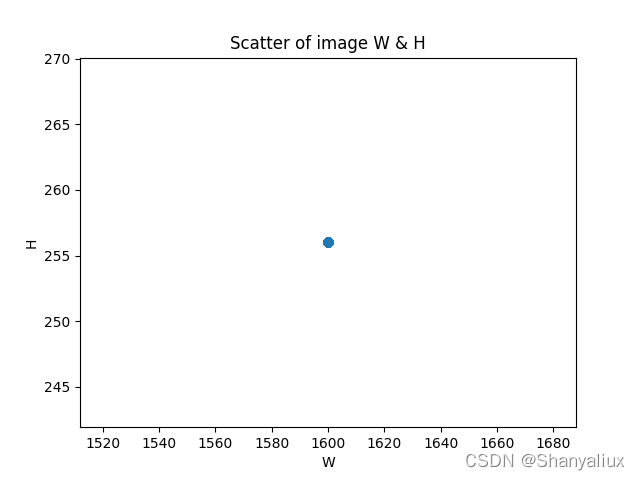
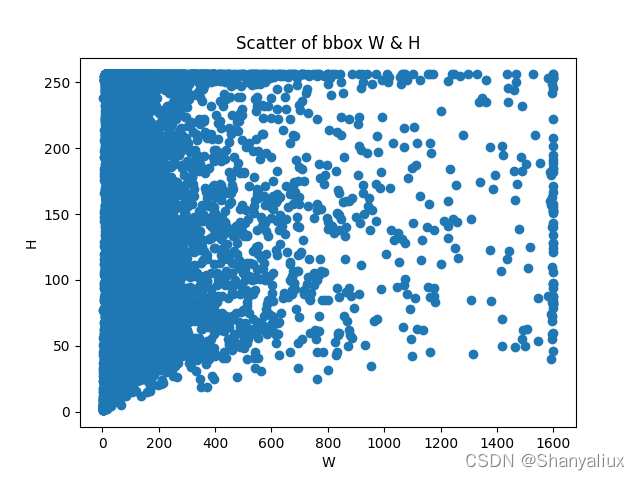
横坐标为比率,纵坐标为数量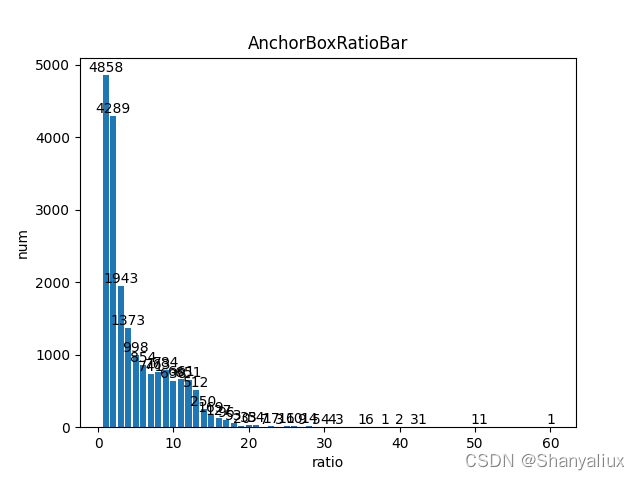
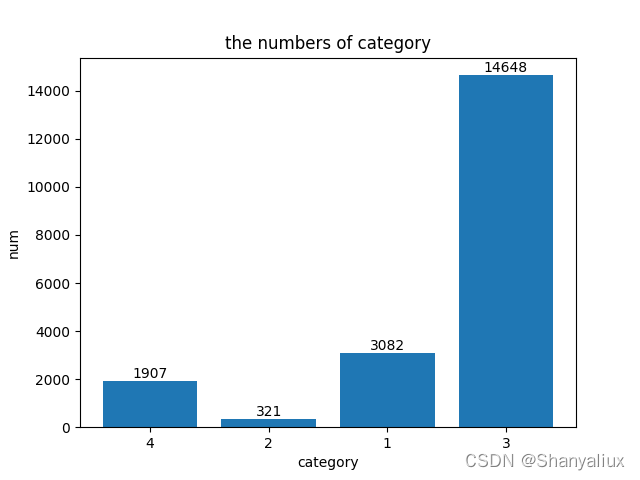
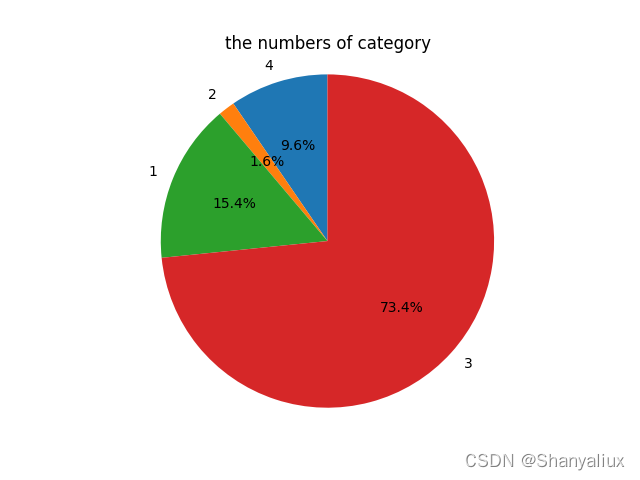
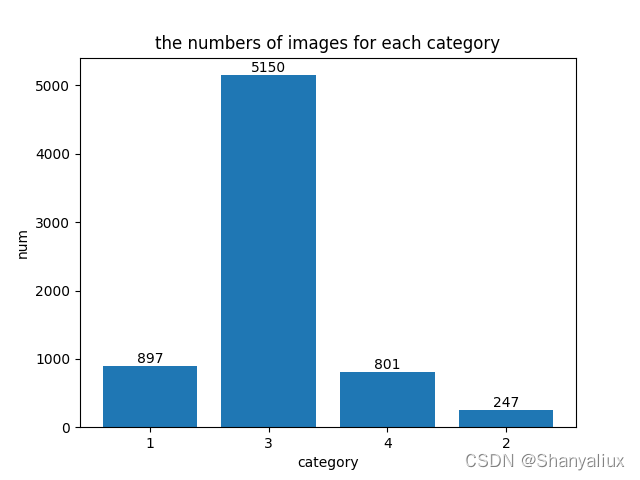
横坐标为一张图片上的标注框数量,纵坐标为图片数量
根据coco的划分规则计算
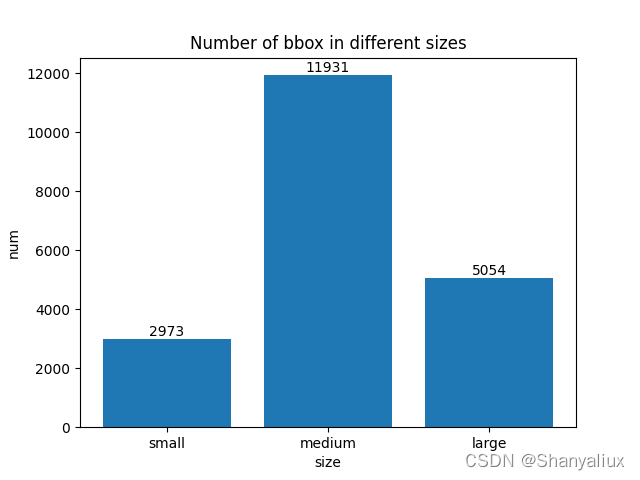
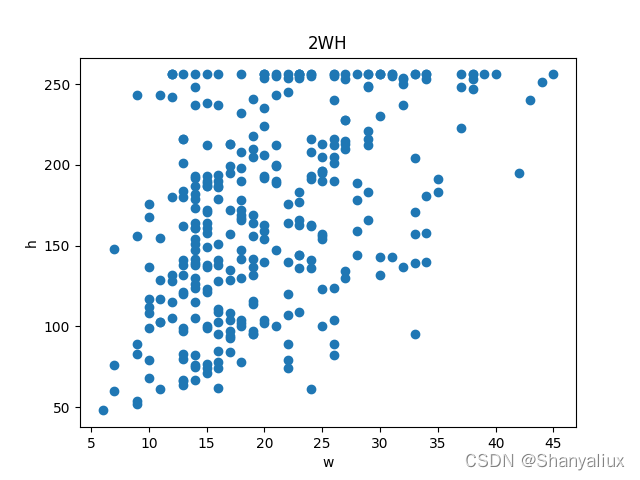
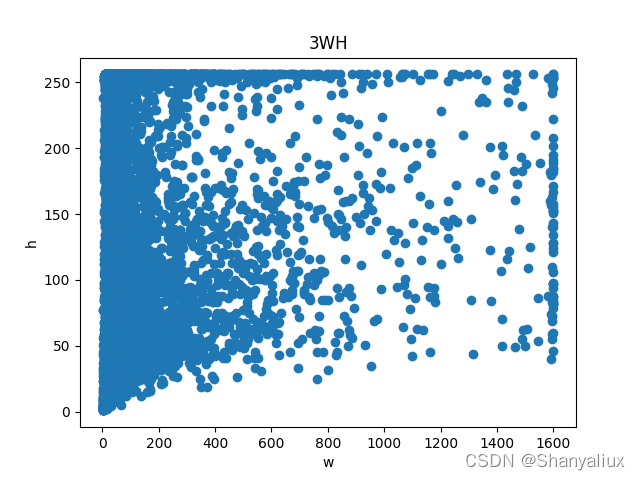
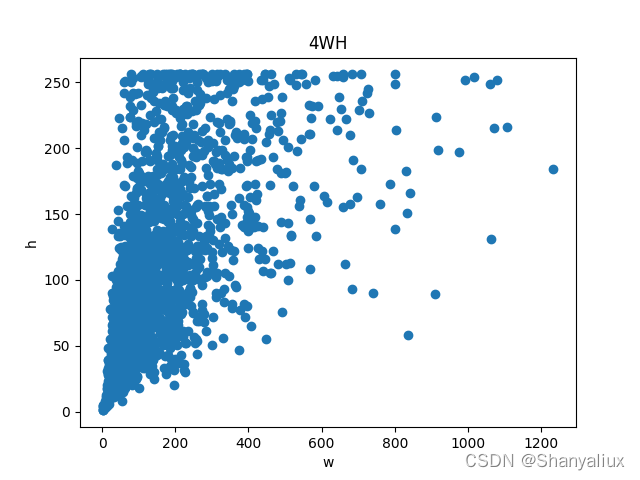
Github
git clone https://github.com/Shanyaliux/DataAnalyze.gitcd DataAnalyzepip install -r requirements.txtpython DataAnalyze.py ${type} ${path} [--out ${out}]type The format of the dataset, optional 'coco' or 'voc'.path The path of dataset.type is 'coco', the path is the json file path.type is 'voc', the path is the path of the xml file directory.--out is the output directory, default is './out'python DataAnalyze.py coco ./tarin.json --out ./out/python DataAnalyze.py voc ./xml/ --out ./out/
